
How to Get Images from a Dead HTML?
Last Updated on May 5, 2025 by Jim C.
Retrieving images from a “dead” HTML page—meaning a webpage that is no longer active on the internet—can be an essential task for data recovery, web development, or content management. This guide outlines methods for extracting images from such pages, with an emphasis on practical steps and tools.
Know the Challenge
When a webpage is considered “dead,” it typically means the server hosting the content is no longer functioning, or the page itself has been removed. In such cases, the HTML file might still be accessible from a local copy, or cached versions may exist on the internet.
Using Browser Cache
One of the most straightforward methods to recover images from a dead HTML page is through your browser cache. This is a temporary storage location where web browsers keep copies of images, scripts, and other web content items to load pages more quickly:
- Locate Browser Cache:
- For Google Chrome, type
chrome://cachein the address bar. - For Firefox, type
about:cacheand look for the cache entries related to the desired webpage.
- For Google Chrome, type
- Extract Images:
- Search through the cache for entries corresponding to the images you want to recover. The files can often be saved directly from this cache view.
Using Web Archives
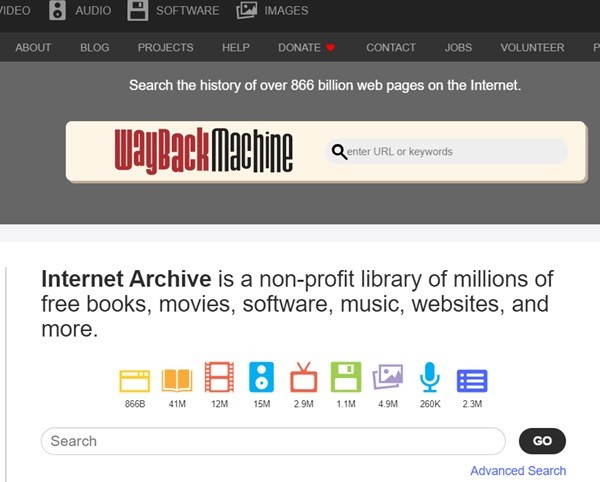
If the browser cache does not yield results, another potent resource is web archives like the Wayback Machine. These services crawl and index the web, storing snapshots of web pages at various times:
- Search the Archive:
- Visit
archive.organd enter the URL of the dead webpage. - Browse through the historical snapshots to find a version of the page that includes the images.
- Visit
- Download Images:
- Right-click on the image in the snapshot and choose “Save image as…” to download it.
HTML File Analysis
If you have a local copy of the HTML file or can access the source code from a cached version, you can manually extract the image URLs:
- Inspect HTML Code:
- Open the HTML file in a text editor or an IDE.
- Search for
<img>tags, which are used to embed images. Thesrcattribute of these tags typically contains the URL of the image.
- Download Images from URLs:
- If the URLs are absolute paths, you access the images if they are hosted at the same location.
- If the URLs are relative paths, you will need the base URL of the original website, or you might reconstruct the path based on the known structure of the website.
Using Third-party Software
Several third-party tools and software are designed for offline browsing and website downloading that can also be used to extract images:
- HTTrack:
- A free utility that downloads a website from the internet to a local directory, building recursively all directories and retrieving HTML, images, and other files from the server to your computer.
- Useful for extracting content from a fully downloaded website.
- WebCopy:
- Copies websites to your local hard disk for offline access.
- It can be configured to download only images or specific types of files from a website structure.
Conclusion
Recovering images from a dead HTML page can involve multiple methods, depending on the availability of the page’s data and the tools at your disposal. Whether utilizing browser caches, web archives, directly analyzing HTML files, or employing specialized software, each approach offers a viable means to reclaim lost visual content. For best results, a combination of these methods may be necessary, especially if some parts of the webpage are harder to recover than others.
FAQs
How do I retrieve an image from HTML?
To retrieve an image from HTML, inspect the webpage’s source code and look for <img> tags. The src attribute inside these tags contains the URL to the image. You can access the image by entering this URL directly into your browser’s address bar.
How do I get an image from a file in HTML?
To display an image stored locally in HTML, use the <img> tag with the src attribute pointing to the file’s path. For example: <img src="path/to/your/image.jpg">. Ensure the path is relative to the HTML file or an absolute path on your server.
How do I take an image source in HTML?
To use an image source in HTML, place the URL or path of the image in the src attribute of an <img> tag. Example: <img src="http://example.com/image.jpg">. This tells the browser where to find and how to display the image on the webpage.
What are some tools to recover images from a dead HTML?
Some tools to recover images from a dead HTML include:
- MiniTool Mobile Recovery for Android: This software is designed to recover data from dead phones, including photos, videos, messages, and more. It requires the phone to be rooted and USB debugging enabled.
- applexsoft Photo Recovery: This tool is effective for recovering lost image files, photos, and damaged pictures from memory cards and digital cameras.
- MiniTool Power Data Recovery: This software can retrieve various file types, including graphic and picture files like JPG, JPEG, TIFF, PNG, GIF, and more. It offers a free version for up to 1 GB of data recovery.
- PhotoRec: An open-source utility that specializes in recovering pictures, videos, and other common file formats from hard drives, memory cards, and digital cameras. It recognizes over 480 file extensions and runs on various operating systems.
- Disk Drill: This tool is known for recovering files from external hard drives and offers features like file preview capabilities and support for BitLocker-encrypted drives.
By using these tools, you can effectively recover images from a dead HTML.
What are some signs that an HTML file is dead?
Some signs that an HTML file is dead include:
- Links Not Working: Dead HTML files often contain links that do not lead to any valid web pages or resources.
- Obsolete Content: Outdated or irrelevant information within the HTML file can indicate that it is no longer actively maintained or updated.
- Lack of Interactivity: Dead HTML files may lack interactive elements or functionality, appearing static and unresponsive.
- No Recent Updates: If the HTML file has not been updated or modified for a long time, it could suggest that it is no longer in use or maintained.
- Broken Design: Visual cues like broken layouts, missing images, or distorted formatting can be signs of a dead HTML file.
By observing these indicators, you can identify when an HTML file is no longer functional or actively used.
About the Author Jim C.
Jim C. Clark is the lead tech blogger at TechnoHacks.net, where he delivers insightful content across a wide range of digital topics. With a keen interest in emerging technology and practical tools, Jim writes in-depth articles on AI, Python, software, and the latest apps. He also shares expert advice on freelancing, digital marketing, SEO, and business growth strategies. Known for his clear, engaging writing style, Jim breaks down complex concepts into actionable insights. Whether he's recommending the best free tools 🧰 or explaining “how to” guides, Jim’s goal is to empower readers with the knowledge they need to thrive in the digital world.